
Intermediate Representations
Why an IR at All
Whether a compiler is six lines or six million, it lowers through at least one intermediate form — because IRs make hard things easy.
Reuse Across Fronts and Backs
One IR plus N back-ends means each new target needs no front-end work, and each new language needs no back-end work (LLVM exists because of exactly this).
A Substrate for Analysis
Simplified programs are analyzable programs: dataflow, liveness, and type reasoning all run on the IR, not on the surface syntax.
The IR Ladder
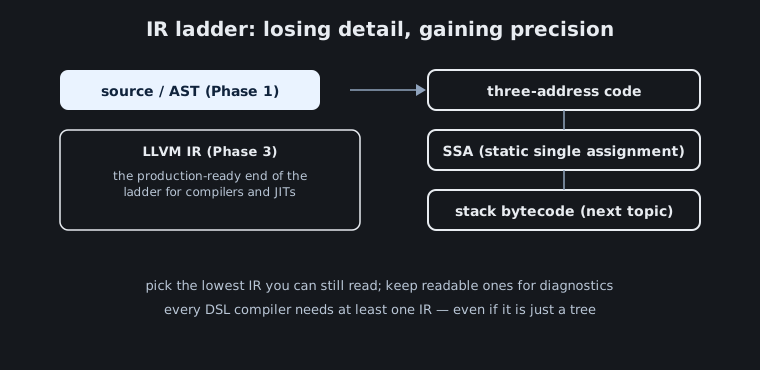
Figure 1 — Lower IRs add machine detail; higher IRs keep meaning. Pick the lowest one you can still read.
Trees (the AST itself)
The checked AST is already an IR: readable, debuggable, and directly interpretable (tree-walking). For small DSLs it is the only IR needed.
Three-Address Code
Statements of the form t1 = t2 op t3 — at most one operator per line, temporaries between results. The sweet spot for generating both bytecode and native code.
SSA Form
Every variable is assigned exactly once; joins use phi nodes. This is what makes optimization sound and fast (LLVM IR is SSA — Phase 3).
Stack Bytecode
Instructions push and pop an operand stack (this roadmap’s Bytecode & Codegen topic); compact and trivial to interpret.
Choosing Your IR
DSL-Scale Guidance
Start with the checked AST (free — you already have it) and add lower IRs only when a need appears: a bytecode target, an optimizer, or a native back-end. The IR ladder is climbed downward one rung at a time, never all at once.
Readability Is a Requirement
Every IR worth shipping has a textual dump format: --dump-ir or a dot renderer. If you cannot print the IR, you cannot debug the compiler.
Example: Lowering an Expression
The same expression in two worlds: the AST from Parsing & Trees and the three-address code that will feed Bytecode & Codegen.
AST -> TAC (commented)
# three-address: one operation per line, fresh temporaries
t1 = 2 * 3          ; the multiplication binds tighter
t2 = 1 + t1         ; addition last, by precedence
store result, t2    ; or: PUSH 1 PUSH 2 PUSH 3 MUL ADD
How to Read It
Notice how 1 + 2 * 3 becomes a sequence of two tiny statements: one operator each, no nesting. That flatness is what every later pass (emit, optimize, register-allocate) wants to consume.
Next Steps
Continue Phase 2
With an IR, pick a target: Interpreters walk trees, Bytecode & Codegen flatten to instruction lists, and Code Generation reaches native code.