
Strings & Text
s[3] on "héllo" does not return a character, it raises StringIndexError.
This lesson builds text handling from the inside out. First you learn what a string really is and how to inspect one, so indexing stops being guesswork. Then you assemble, search, and transform text with the standard library, and finally you look at the two subjects that separate beginners from engineers: building long output without quadratic copying, and keeping byte positions and character positions apart.
The String Model
Before you call a single function you need a mental model of what sits in memory when you write "hello". Julia's model is deliberately simple: a String is an immutable sequence of UTF-8 code units, and every index into it is a byte offset.
Strings Are Immutable
You cannot change a character inside a string. There is no s[1] = 'H'. Any transformation produces a new string, and the old one stays untouched until the garbage collector reclaims it. This is why passing strings around is cheap: every function that receives one knows it can never be modified underneath it.
# Assignment copies the reference, not the text
s = "hello"
t = s                 # t and s refer to the same immutable text
t == s                # true

# There is no character assignment
s[1] = 'H'            # ERROR: MethodError — setindex! is not defined for String

# You build a new string instead
u = uppercase(s)      # "HELLO"
s                     # "hello" — unchanged

# The identity check shows the new object
u === s               # false — different strings
Because the text cannot change, the compiler may store a literal once and reuse it, and library functions may return views into your existing string instead of copies. The third chapter shows both effects in action.
UTF-8 and Code Units
Julia stores text as UTF-8 bytes. ASCII characters use one byte each, most Latin, Greek, and Cyrillic characters use two, and most CJK characters use three. A single character — what Julia calls a Char, one Unicode code point — therefore occupies between one and four bytes.
That is the entire source of the indexing surprise, and the diagram below makes it concrete for the word "héllo".
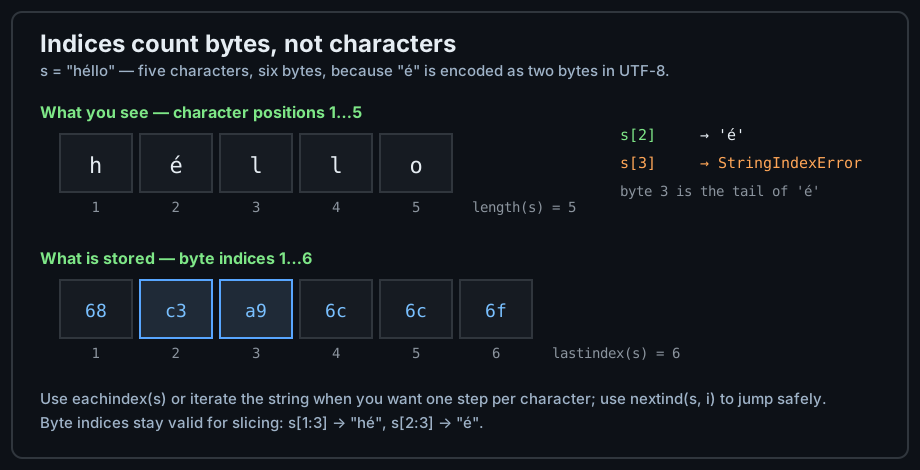
length counts characters, indices address bytes.Keep two numbers apart from now on: length(s) counts characters, while lastindex(s) gives the byte offset of the last character. For ASCII text the two numbers are equal, which is exactly why the bug hides during testing and appears in production when someone types an accented word.
Inspecting a String
When text misbehaves, do not guess — ask. Julia exposes the type, the character count, the byte count, and the raw bytes of any string, which is usually enough to explain the symptom immediately.
s = "héllo"

typeof(s)             # String
length(s)             # 5  — characters
ncodeunits(s)         # 6  — bytes actually stored
sizeof(s)             # 6  — memory used; equal to ncodeunits for String
lastindex(s)          # 6  — byte index of the last character
isvalid(s, 3)         # false — byte 3 is the continuation byte of "é"
isvalid(s, 2)         # true  — byte 2 starts the character "é"

# The raw bytes, written in hexadecimal
collect(codeunits(s)) # UInt8[0x68, 0xc3, 0xa9, 0x6c, 0x6c, 0x6f]

# The characters, as Char values
collect(s)            # ['h', 'é', 'l', 'l', 'o']

# A one-line summary, useful for long strings
summary(s)            # "5-character String"

# Escapes let an ASCII source file hold non-ASCII text safely
"\u00e9"              # "é" — the same character, written by code point
"\x41"                # "A" — written by byte value
isvalid(s, i) answers the only question that matters before indexing: is byte i the start of a character? Chapter 3 turns that into a probing rule you can apply to any loop.
String, SubString, and Char
Three types carry what beginners call "text". Knowing which one a function returns tells you whether you hold an owned string, a window, or a single character — and therefore whether you are paying for a copy.
| Type | What it holds | Copies text? | Typical source |
|---|---|---|---|
String | An immutable UTF-8 string owned in memory | It holds the bytes | "text", join, uppercase |
SubString | A window into an existing string plus a byte range | No — it shares the parent | view, split, chop |
Char | One Unicode code point (1 to 4 bytes) | No — a value type | s[1], iterating a string |
Vector{Char} | A mutable array of code points | Yes — an array of values | collect(s) |
s = "Julia rocks"

c = s[1]                   # 'J' — a Char
typeof(c)                  # Char

sub = SubString(s, 1, 5)   # "Julia" — a window, no copy
typeof(sub)                # SubString{String}
String(sub)                # "Julia" — materialise a copy when you need one

# Comparison across the three types is value-based
c == 'J'                   # true
sub == "Julia"             # true — SubString compares by content
A SubString is why splitting a large document into words is cheap: split(text) returns windows into text rather than thousands of separate strings. The trade-off is that a view keeps its parent alive — retain one word and the whole document stays in memory.
Building Strings
You now know what text is. The next question is how to assemble it from parts, because the way you compose strings decides how readable your code is and — in loops — how fast it runs.
Concatenation and Repetition
Two operators join strings, and the choice between them is not cosmetic. * concatenates and returns a String; repeat and ^ duplicate. Note that + is deliberately absent: Julia keeps + for arithmetic so that adding text is never accidental.
first = "Julia"
last  = "rocks"

# Concatenation uses *, not +
greeting = first * " " * last       # "Julia rocks"

# + on strings is an error — a deliberate design choice
"a" + "b"                           # ERROR: MethodError

# Repetition
"ab" ^ 3                            # "ababab"
repeat("-", 20)                     # "--------------------"
repeat(["a", "b"], 3)               # ["a", "b", "a", "b", "a", "b"]

# An array of strings joins into one string
join(["Julia", "rocks"])            # "Juliarocks"
join(["Julia", "rocks"], " ")       # "Julia rocks"

# Useful one-liners
length(first * last)                # 10
*("a", "b", "c")                    # "abc" — the function form splats freely
When you chain more than three pieces, stop using * and use interpolation or join. A line of five * operators is hard to read and easy to mistype.
Interpolation and string()
Interpolation embeds a value directly inside a literal with $. It calls print on the value, so you get the text form, not the quoted form. This is the idiomatic way to compose messages, build labels, and format quick diagnostics.
name  = "Ada"
count = 3

# $ for a simple variable
"Hello, $name!"                     # "Hello, Ada!"

# $( ) for an expression
"$name has $(count + 1) tasks"      # "Ada has 4 tasks"
"$(uppercase(name))"                # "ADA"

# $print vs $show: print gives the text, show gives the literal form
"$name"                             # "Ada"
"$(repr(name))"                     # "\"Ada\"" — includes the quotes

# A literal $ is escaped with $
"cost: \$5"                         # "cost: $5"

# string() is the function form — same rules, usable with any number of arguments
string("total: ", count)            # "total: 3"
string(1, "+", 2, "=", 1 + 2)       # "1+2=3"

# Interpolation of a vector prints the whole array
values = [1, 2, 3]
"values = $values"                  # "values = [1, 2, 3]"
Interpolation is not string formatting with padding or decimals — for that, Chapter 6 introduces Printf. Interpolation answers "what is this value", Printf answers "how should this value be laid out".
Joining Collections
Real programs rarely have two strings; they have a collection of them — words, lines, fields, log records. join turns any iterable into one string with an optional separator, and it is the function you want instead of a concatenation loop.
words = ["alpha", "beta", "gamma"]

join(words)                         # "alphabetagamma"
join(words, ", ")                   # "alpha, beta, gamma"
join(words, ", ", " and ")          # "alpha, beta and gamma" — separator and last

# Join with the empty separator to compose a fixed string
join(["2026", "09", "12"], "-")     # "2026-09-12"

# Works on any iterable of values, not only strings
join(1:5, "+")                      # "1+2+3+4+5"

# Build a CSV line from a row of numbers
row = [3, 8, 12]
join(row, ",")                      # "3,8,12"

# A dictionary joins as key-value pairs
join(Dict("a" => 1), ", ")         # "a => 1"

# join is also the fastest way to merge a long vector of strings
lines = ["line $i" for i in 1:1000]
join(lines, "\n") |> length         # length of the merged text
The last example is the important one: join allocates the result once, while a loop that concatenates grows the string a thousand times. Chapter 6 explains the cost curve.
Indexing and Iteration
Indexing is where strings stop being friendly. Julia asks you to be precise about whether you are addressing a byte or a character, and rewards that precision with zero-copy slicing. This chapter gives you the three patterns that cover every real case.
Indexing Without Breaking Unicode
Square brackets take a byte index and require it to be the start of a character; anything else throws StringIndexError. The safe approach is to compute a position with nextind instead of adding one, or to test with isvalid before you index.
s = "héllo"

# Works: byte 2 starts "é"
s[2]                  # 'é'

# Fails: byte 3 is inside "é" — this is a StringIndexError, not a wrong character
s[3]                  # ERROR: StringIndexError("héllo", 3)

# Safe navigation: nextind jumps to the start of the NEXT character
i = firstindex(s)     # 1
i = nextind(s, i)     # 2 — "é" lives here
i = nextind(s, i)     # 4 — skipped over both bytes of "é"
prevind(s, i)         # 2 — jump back one character

# Defensive form when the position comes from outside your code
function char_at(s, byte)
    isvalid(s, byte) ? s[byte] : ''
end
char_at(s, 2)         # 'é'
char_at(s, 3)         # '' — the caller gets a sentinel instead of a crash

# The same rule applies to the last character of a UTF-8 string
s[end]                # 'o' — end is the last VALID byte index, not length(s)
s[length(s)]          # 'l' — different position: length counts characters
The last two lines are worth memorising: s[end] is always the final character, but s[length(s)] is only the final character while the text is pure ASCII.
Iterating over Characters
Iteration is the safe, allocation-free way to walk text: for c in s yields Char values and handles multi-byte sequences for you. Use eachindex when you also need positions, and never use 1:length(s) as an index range on arbitrary text.
s = "héllo"

# The idiomatic loop — one step per character
for c in s
    print(c, ' ')             # h é l l o
end

# Position plus character
for i in eachindex(s)
    println(i, " => ", s[i])  # 1=>h 2=>é 4=>l 5=>l 6=>o  (byte indices!)
end

# Counting something while iterating
vowels = count(c -> c in "aeioué", s)   # 2

# Numbering the characters with their ordinal position
for (n, c) in enumerate(s)
    println(n, ':', c)        # 1:h 2:é 3:l 4:l 5:o  (ordinals, not bytes)
end

# Character types you can test
isletter('é')                 # true
isdigit('7')                  # true
isuppercase('J')              # true
isspace(' ')                  # true

# Collecting into an array gives a mutable structure of code points
chars = collect(s)
reverse!(chars)               # ['o', 'l', 'l', 'é', 'h']
String(chars)                 # "olléh"
enumerate and eachindex are not interchangeable: enumerate counts characters from one, while eachindex produces byte indices. Mixing them up is the most common source of StringIndexError in beginner code.
Slicing and SubStrings
A slice with a range returns a new String; view returns a SubString that shares memory. Both accept byte ranges, and both require the endpoints to sit on character boundaries. Functions such as first, last, chop, and chomp express the common cases without index arithmetic.
s = "Julia rocks"

# Byte ranges — endpoints must be character starts
s[1:5]                # "Julia"
s[7:end]              # "rocks"
s[end-4:end]          # "rocks"

# view shares memory; slice copies
u = view(s, 1:5)      # SubString — no allocation
String(u)             # "Julia" — allocate only when you must

# Named helpers beat index arithmetic
first(s, 5)           # "Julia"
last(s, 5)            # "rocks"
chop(s)               # "Julia rock"  — drop the last character
chop(s; tail = 6)     # "Julia"
chomp("done\n")       # "done" — drop one trailing newline

# Padding and trimming for fixed-width output
lpad("7", 3, '0')     # "007"
rpad("7", 3)          # "7  "
strip("  padded  ")   # "padded"
strip("xxhixx", 'x')  # "hi"
Because a slice copies, a loop that slices inside itself can quietly copy the whole document many times. Use view when you only read, and materialise with String(...) when the result must outlive the parent.
Searching and Comparing
Searching text means asking a question and getting a position back — usually a byte index you will hand to a slice or a view. Comparing text means deciding equality or order, and Julia makes the distinction between "same characters" and "same bytes" explicit.
Finding Text
The search functions return nothing when they fail, not -1. That is a real advantage: nothing cannot be mistaken for a position, so the compiler forces you to handle the failure before you use the result.
| Function | Answers | Returns |
|---|---|---|
occursin(needle, hay) | Does it appear at all? | Bool |
findfirst(needle, hay) | Where is the first occurrence? | Range or nothing |
findlast(needle, hay) | Where is the last occurrence? | Range or nothing |
findnext(needle, hay, start) | Where is the next one from a position? | Range or nothing |
startswith / endswith | Does it begin or end with this? | Bool |
count(needle, hay) | How many occurrences? | Int |
text = "Julia is fast. Julia is friendly."

occursin("fast", text)              # true
startswith(text, "Julia")           # true
endswith(text, ".")                 # true
count("Julia", text)                # 2

# Positions come back as ranges, which you can slice directly
r = findfirst("fast", text)         # 10:13
text[r]                             # "fast"

# Failure is nothing — the safe branch is explicit
findfirst("slow", text)             # nothing
pos = something(findfirst("slow", text), 1:-1)   # fall back to an empty range

# Walk every occurrence with findnext
i = findfirst("Julia", text)
while i !== nothing
    println("found at ", first(i))
    i = findnext("Julia", text, last(i) + 1)
end

# Case-insensitive work: normalise first, or use a regex (Chapter 5)
occursin("JULIA", uppercase(text))  # true
Because findfirst returns a range, the idiomatic "find and extract" is two steps that never risk an off-by-one: r = findfirst(...), then text[r].
Comparison Rules
String equality compares content, and ordering compares code points, not human-language collation. That is the correct default for programming tasks such as sorting identifiers, and the wrong tool for sorting display names — for those, normalise the text first.
a = "Julia"
b = "Julia"
c = "julia"

a == b                # true  — same characters
a == c                # false — capital J is a different code point
a === b               # true here (literal deduplication); do not rely on it
isequal(a, c)         # false — isequal equals == for strings, unlike for floats
cmp(a, c)             # -1 — negative means a sorts before c

# Ordering follows Unicode code points
'J' < 'j'             # true — uppercase comes before lowercase
sort(["beta", "Alpha", "gamma"])        # ["Alpha", "beta", "gamma"]
sort(["beta", "Alpha"], by = lowercase) # ["Alpha", "beta"] — case ignored
sort(["beta", "Alpha"], rev = true)     # ["beta", "Alpha"]

# Normalising before comparison makes case-insensitive matching easy
lowercase(a) == lowercase(c)            # true
minimum(["B", "a"])                     # "B" — code point order
minimum(["B", "a"]; by = lowercase)     # "a" — human order

# Comparing a string with a Char works by value
"J" == 'J'            # false — a String is never equal to a Char
"J"[1] == 'J'         # true
Watch the last trap: "J" == 'J' is false. A one-character string is not a character, and comparing them is a type mismatch that Julia answers honestly instead of guessing.
Transforming Text
Everything so far reads text. Now you rewrite it. The four families you need are splitting, replacing, case conversion, and pattern substitution — and in Julia each one has a single recommended function rather than five competing ones.
split, rsplit, and partition
split cuts a string into pieces and returns views into it, so it is fast even for large documents. Use the two-argument form to keep the separators out, and add limit or keepempty when the data has trailing or consecutive separators.
csv = "id,name,qty"

split(csv, ",")                # ["id", "name", "qty"] — SubStrings
split("a,b,,c", ",", keepempty = false)   # ["a", "b", "c"]
split("k=v", "=", limit = 2)   # ["k", "v"] — useful for key=value pairs

# Split on whitespace by default, which handles messy input
split("  alpha   beta\tgamma  ")          # ["alpha", "beta", "gamma"]

# Split a multi-line text into lines
text = "first\nsecond\nthird"
split(text, "\n")              # ["first", "second", "third"]
eachline(IOBuffer(text)) |> collect      # same result, streaming form

# rsplit splits from the right — perfect for file extensions
rsplit("archive.tar.gz", ".", limit = 2)  # ["archive.tar", "gz"]

# partition keeps the separator and returns three parts
partition("user@example.com", "@")        # ("user", "@", "example.com")

# Rebuild with join, the natural partner of split
join(split(csv, ","), " | ")              # "id | name | qty"
split plus join is how you normalise delimited data: split once, transform the fields, join once. No concatenation loop, no manual index tracking.
replace, Case, and Strip
replace takes a string or a character mapping and returns a new string. Give it a pair for one substitution or a function for a rule that decides per match. Case conversion returns new strings as well, so it never mutates the original.
s = "The Quick Brown Fox"

replace(s, "Quick" => "Slow")     # "The Slow Brown Fox"
replace(s, " " => "_")            # "The_Quick_Brown_Fox"
replace(s, ['a', 'i'] => '*')     # "The Qu*ck Brown Fox"

# A function decides what each match becomes
replace("v1 and v2", r"v(\d)" => s"version\1")   # "version1 and version2"
replace("abc", 'b' => m -> "")                  # "ac" — one character removed

# Case conversion
uppercase(s)                      # "THE QUICK BROWN FOX"
lowercase(s)                      # "the quick brown fox"
titlecase("julia rocks")          # "Julia Rocks"
uppercasefirst("julia")           # "Julia"

# Stripping and cleaning
strip("\t padded \n")             # "padded"
lstrip("00042", '0')              # "42"
rstrip("12.50")                   # "12.50"; rstrip("12.50", '0') → "12.5"

# Cleaning a messy CSV field in one pipeline
raw = "  Ada Lovelace  "
clean = strip(raw) |> lowercase |> x -> replace(x, " " => "_")
clean                             # "ada_lovelace"
The pipeline at the end is the pattern to remember: small single-purpose functions chained with |> read exactly like the transformation they perform.
Pattern Matching with Regex
When the search target is a shape rather than a literal, use a regular expression. Julia's r"..." literal compiles the pattern once and is the only place where regex syntax is visible in your code; every other function takes the result as an ordinary value.
log = "2026-09-12 ERROR db timeout"

# A literal pattern with named groups
m = match(r"(?<date>\d{4}-\d{2}-\d{2}) (?<level>\w+)", log)
m[:date]                     # "2026-09-12"
m[:level]                    # "ERROR"
m.match                      # the whole match

# Every match in a string
occursin(r"ERROR|WARN", log)         # true
count(r"\d", log)                    # 8 — every digit
collect(eachmatch(r"\d+", log))      # three matches: "2026", "09", "12"

# Captures from a pattern built at runtime
p = Regex("(\\d+)-(\\d+)")           # escapes are doubled when not using r""
m2 = match(p, "12-34")
m2.captures                  # ["12", "34"]

# Substitution with capture references
replace(log, r"ERROR" => "E")        # "2026-09-12 E db timeout"
replace(log, r"(?<level>\w+)" => s"level=\g<level>")   # inserts the group

# Split on a pattern rather than a literal
split("a1b22c333", r"\d+")          # ["a", "b", "c"]
Two regex details matter in practice: names are nicer than numbers for captures, and a regex error at runtime means the pattern was built as a string — prefer the r"..." form so mistakes surface when the file is loaded, not when a user hits that branch.
Efficient Building and Formatting
This chapter is about the difference between code that works on a test string and code that survives a million rows. Two habits do most of the work: build text once instead of growing it, and separate the value from its layout.
The Cost of Concatenation
A String is immutable, so every * or interpolation in a loop allocates a new string and copies everything before it. Ten thousand appends copy roughly the sum of all lengths seen so far — quadratic work, and the classic reason a text report becomes slow.
# Quadratic: each step copies everything already collected
function slow_report(n)
    out = ""
    for i in 1:n
        out = out * "line $i\n"      # a new String every iteration
    end
    out
end

# Linear: collect the pieces, then join once
function fast_report(n)
    parts = Vector{String}(undef, n)
    for i in 1:n
        parts[i] = "line $i"
    end
    join(parts, "\n")
end

# A comprehension plus join is the shortest correct form
join(["line $i" for i in 1:1000], "\n") |> length

# Measured difference (Julia 1.10, 100_000 lines) — indicative, not a benchmark
@time slow_report(100_000)     # large allocation, most time in copying
@time fast_report(100_000)     # one allocation for the joined result
The rule to carry into your own code: inside a loop, collect strings in a vector and join afterwards, or write into an IOBuffer. Reserve * for composing a handful of pieces on one line.
IOBuffer, Printf, and Formatted Output
When you are streaming rather than assembling, an IOBuffer is the right tool: it is a resizable byte buffer you print into, and String(take!(buf)) hands you the final text. When you need fixed-width columns or decimals, Printf gives you the classic % specifiers.
using Printf      # the @printf and @sprintf macros live in a stdlib package

# Printf controls the layout, not the value
@sprintf("%d items at %.2f each", 3, 19.5)      # "3 items at 19.50 each"
@sprintf("%-10s|%5.1f", "total", 19.5)          # "total     | 19.5"
@sprintf("%08.2f", 3.14159)                     # "00003.14"
@printf("row %d: %s\n", 1, "ready")             # writes straight to stdout

# A buffer collects many writes, then becomes one string
buf = IOBuffer()
for i in 1:3
    println(buf, "line ", i)                    # no intermediate string
end
String(take!(buf))            # "line 1\nline 2\nline 3\n"

# Writing a formatted table without any intermediate strings
report = IOBuffer()
for (name, qty) in [("bolts", 12), ("nuts", 7)]
    @printf(report, "%-8s %4d\n", name, qty)
end
String(take!(report))         # "bolts      12\nnuts        7\n"

# print, println and show differ: only show adds quotes and escapes
print("a\nb")                 # ab
show("a\nb")                  # "a\nb"
repr("a\nb")                  # "\"a\\nb\"" — the quoted literal form
Use Printf for columns and precision, interpolation for messages, show/repr when output must be copy-pasteable back into code, and an IOBuffer when many pieces are involved.
Parsing Text Back to Numbers
Text that arrives from files, forms, and networks is text until you convert it. parse performs that conversion and throws on failure, while tryparse returns nothing — and that difference is your error-handling strategy in one line.
parse(Int, "42")              # 42
parse(Float64, "3.14")        # 3.14
parse(Bool, "true")           # true
parse(Int, "0x1f"; base = 16) # 31

# Failure is loud — good inside validated data paths
parse(Int, "abc")             # ERROR: ArgumentError

# Failure is quiet — good for untrusted input
tryparse(Int, "abc")          # nothing
tryparse(Int, "42")           # 42
qty = something(tryparse(Int, "abc"), 0)   # 0 — a safe default

# Round trips: text in, value, text out
x = parse(Float64, "19.50")   # 19.5
@sprintf("%.2f", x)           # "19.50" — back to the original layout

# Converting one character is a value operation, not parsing
Int('7') - Int('0')           # 7 — the digit's numeric value
'7' in '0':'9'                # true — a range of characters works
Reach for tryparse whenever the text comes from outside your program, and parse when a failure means your own invariants are broken and should be visible.
Common Pitfalls
Three mistakes account for most text bugs in Julia: confusing byte positions with character positions, expecting comparisons or conversions to behave like other languages, and using missing where an empty string was meant. Each has a short, reliable fix.
Byte Positions versus Character Positions
Any function that returns a character count cannot be used as a byte index, and any loop written as 1:length(s) is wrong for non-ASCII text. The fix is to choose the right iterator at the start: iterate characters when you need characters, and eachindex when you need positions.
s = "café au lait"          # 12 characters, 13 bytes

# Wrong: length is a character count used as a byte index
for i in 1:length(s)
    s[i]                    # eventually StringIndexError at the "é"
end

# Right: eachindex yields valid byte positions
for i in eachindex(s)
    s[i]                    # always a Char
end

# Right: iterate the string when you only need characters
n = count(isletter, s)      # 10 — letters, counted without any index
n

# Byte-safe slicing: both endpoints must sit on character boundaries
isvalid(s, 4)               # true  — byte 4 starts "é"
isvalid(s, 5)               # false — byte 5 is inside "é"
s[1:3]                      # "caf"  — safe, ends on a boundary
first(s, 4)                 # "café" — four CHARACTERS, bytes handled for you
If you need "the first N characters", use first(s, N); if you need "the first N bytes", use view(s, 1:N) and check isvalid. Both intentions are legitimate — the bug is leaving the choice implicit.
Equality and Ordering Traps
Text comparisons are value comparisons, and Julia never guesses at your intent. Four cases bite most often, and each has one correct form.
| Looks right | Reality | Do this instead |
|---|---|---|
"J" == 'J' | false — different types | s[1] == 'J' |
"a" + "b" | MethodError — + is numeric | "a" * "b" |
"A" == "a" | false — case matters | lowercase(a) == lowercase(b) |
sort(names) | Code point order, not human order | sort(names; by = lowercase) |
strip(x) == nothing | Never true — use isnothing | isempty(strip(x)) |
# Case-insensitive comparison without surprises
equals_ignoring_case(a, b) = lowercase(a) == lowercase(b)

# Membership and prefix tests are clearer than manual slicing
startswith("report.pdf", "report")        # true
endswith("report.pdf", ".pdf")            # true

# Empty string versus nothing: two different ideas
isempty("")                # true  — a string with no characters
isnothing(nothing)         # true  — the absence of a value
missing and nothing in Text
missing means "unknown" and nothing means "absent". Both can end up in a text field, and both make ordinary comparisons fail loudly or silently depending on the operator — so normalise at the boundary, not at the point of use.
x = missing

x == "abc"               # missing — not false: the comparison is unknown
ismissing(x)             # true
coalesce(x, "")          # "" — replace missing with a default
skipmissing([missing, "a"]) |> collect      # ["a"]

# A safe normaliser for fields coming from a file
as_string(v) = v isa AbstractString ? String(v) : ""
as_string("ok")          # "ok"
as_string(missing)       # "" — the caller never sees missing
as_string(nothing)       # ""

# Conditional fallback also works for empty text
text = "   "
isempty(strip(text)) ? "(blank)" : text     # "(blank)"
Normalising at the boundary is what keeps the rest of your code free of missing checks: one function decides what an absent value means, and every caller then works with ordinary strings.
String is immutable UTF-8 text, indexed by bytes; length counts characters while lastindex gives the last byte. Iterate with for c in s or eachindex(s), never with 1:length(s). Compose with interpolation and join, split with split, rewrite with replace, and search with occursin/findfirst, remembering that they return nothing on failure. Inside loops, collect pieces and join once — or write into an IOBuffer. Use tryparse for untrusted text and normalise missing at the border of your program.
Text is the first of the abstract types you meet in this phase. Next: Composite Types shows how to define your own types with named fields, so you can stop passing loosely related strings and numbers around separately.