
Web & APIs
HTTP.jl gives you a client and a server in the same process, Genie.jl adds routing, sessions and templates, and the task scheduler from the parallelism lesson handles thousands of concurrent requests without a thread per connection.
This lesson covers both sides of the wire: calling somebody else's API from a script, and exposing your own computation as an endpoint. The second half is where Julia has a genuine advantage — a service that performs a simulation, an optimization, or a statistical model can run that code in-process, with no queue, no serialisation of intermediate state, and no second language in the stack.
HTTP with HTTP.jl
The same package is a client and a server. Starting with the client is the fastest way to learn the API, because you can test against any public service.
Making Requests
HTTP.request handles every verb; HTTP.get and friends are the convenient shortcuts.
using HTTP

# The simplest call
r = HTTP.get("https://httpbin.org/get")
r.status                       # 200
String(r.body)                 # the response body as text

# Any verb, any body
r = HTTP.post("https://httpbin.org/post", ["Content-Type" => "application/json"],
              """{"name": "Ada"}""")
r = HTTP.put("https://httpbin.org/put", [], "payload")
r = HTTP.delete("https://httpbin.org/delete")

# With headers, query parameters and timeouts
r = HTTP.get("https://api.example.com/search";
    query      = ["q" => "julia", "limit" => "10"],
    headers    = ["Authorization" => "Bearer $token", "Accept" => "application/json"],
    readtimeout = 10,
)

# Measure what a slow endpoint costs you
r = HTTP.get("https://api.example.com/slow"; request_timeout = 30)

# Streaming a large response instead of buffering it
open("data.csv", "w") do io
    HTTP.get("https://example.com/big.csv"; response_stream = io)
end
The timeout arguments are not optional in production code. A client without a timeout turns one slow dependency into an outage of your own service, because the request you are waiting on holds a connection of yours.
Reusing Clients and Connections
Recreating a connection for each call wastes a TLS handshake. A persistent client keeps the connection pool warm.
using HTTP

# One client, many requests: the connection is reused
client = HTTP.Client()
for path in ("/a", "/b", "/c")
    r = HTTP.get("https://api.example.com$path"; client = client)
    @info "fetched" path = path status = r.status
end
close(client)

# Or wrap a set of requests in a client block
HTTP.open("GET", "https://example.com") do io
    println(HTTP.get(io; readtimeout = 5))
end

# Retry with backoff — the realistic way to call a flaky endpoint
function get_with_retry(url; attempts = 3, base_delay = 0.5)
    for attempt in 1:attempts
        try
            return HTTP.get(url; readtimeout = 10)
        catch err
            attempt == attempts && rethrow()
            delay = base_delay * 2^(attempt - 1)
            @warn "request failed, retrying" attempt = attempt delay = delay err = err
            sleep(delay)
        end
    end
end

# Retry only what is safe to retry: a GET or an idempotent PUT — never a POST
# that charges a card, unless the API itself supports idempotency keys.
The closing rule matters commercially. Retrying a non-idempotent request is how a payment is taken twice; an idempotency key supplied by the client is how well-designed APIs make that impossible.
Handling Responses and Errors
An HTTP call can fail in three different ways — transport, status code, and body content — and each needs its own handling.
using HTTP, JSON3

function fetch_json(url)
    # 1. Transport errors throw; make them explicit
    r = try
        HTTP.get(url; readtimeout = 10, status_exception = false)
    catch err
        @error "transport failure" url = url err = err
        return nothing
    end

    # 2. Status codes: 4xx is your fault, 5xx is theirs, 3xx is a redirect
    if r.status == 404
        @warn "not found" url = url
        return nothing
    elseif 500 <= r.status < 600
        @error "server error" url = url status = r.status
        return nothing
    elseif r.status != 200
        @error "unexpected status" url = url status = r.status
        return nothing
    end

    # 3. Body content can be malformed even with a 200
    try
        return JSON3.read(String(r.body))
    catch err
        @error "invalid JSON" url = url err = err body = first(String(r.body), 200)
        return nothing
    end
end

# Inspect a response without exceptions, for debugging
r = HTTP.get("https://httpbin.org/status/418"; status_exception = false)
r.status                       # 418
HTTP.header(r)                 # the headers as a Vector of Pairs
Logging the first 200 characters of a malformed body is the detail that turns an hour of guessing into a one-line diagnosis. The service changed its response shape, and the evidence is in the log.
Writing a Service
A server is a function from a request to a response. Everything else — routing, sessions, templates — is convenience built on that idea.
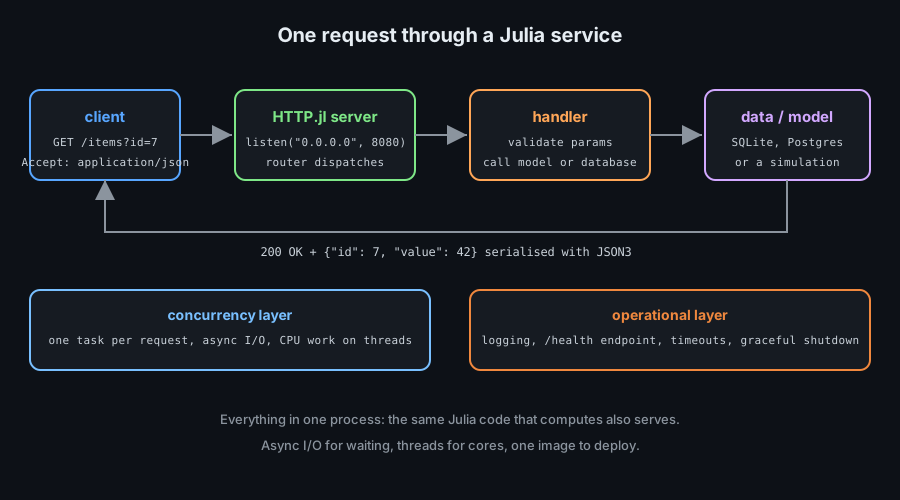
A Server with HTTP.jl Alone
Before reaching for a framework, see how little is required. This is a complete, working JSON API.
using HTTP, JSON3

# Handlers take a request and return a response
function items_handler(req::HTTP.Request)
    params = HTTP.queryparams(HTTP.URI(req.target))
    id = parse(Int, get(params, "id", "1"))

    # ... look the item up ...
    body = JSON3.write((id = id, name = "item-$id", value = id * 6))
    return HTTP.Response(200, ["Content-Type" => "application/json"], body)
end

function health_handler(req::HTTP.Request)
    return HTTP.Response(200, "ok")
end

# Routing is an if-chain until you need something better
function route(req::HTTP.Request)
    if req.method == "GET" && startswith(req.target, "/items")
        return items_handler(req)
    elseif req.method == "GET" && req.target == "/health"
        return health_handler(req)
    else
        return HTTP.Response(404, "not found")
    end
end

# Serve forever, with the router plugged in
HTTP.serve(route, "0.0.0.0", 8080)

# Or serve in the background so the REPL stays usable
server = HTTP.serve!(route, "0.0.0.0", 8080)
close(server)                      # graceful shutdown
This file is worth keeping as a reference: it makes the framework unnecessary for small services, and it makes the framework's behaviour obvious when you do adopt one.
Genie.jl Applications
Genie adds the parts a growing service needs: a router with parameters, controllers, templates, sessions, and a REPL that can edit a running app.
using Genie, Genie.Router, Genie.Requests, Genie.Renderer.Json

# Routes with path parameters and typed access to the request
route("/hello") do
    "Hello, world"
end

route("/items/:id") do
    id = parse(Int, params(:id))
    json((id = id, name = "item-$id"))
end

route("/search", method = GET) do
    q = getpayload(:q, "")
    json((query = q, results = String[]))
end

# Group routes under a common prefix and a common pipeline
route("/api/v1/health") do
    json((status = "ok", version = "1.0.0"))
end

# A controller class keeps handlers out of the routes file
module ItemsController
using Genie.Router, Genie.Requests, Genie.Renderer.Json

function index()
    json((items = [], total = 0))
end

function show()
    id = parse(Int, params(:id))
    json((id = id))
end
end

route("/items", ItemsController.index, method = GET)
route("/items/:id", ItemsController.show, method = GET)

# Start the server (or `up()` in the REPL to reload on change)
Genie.up(8080)
The up() workflow is what makes Genie pleasant during development: routes and handlers reload without restarting the process, so the edit-test loop is measured in seconds rather than in precompilation time.
Templates and Static Files
When the service must also serve pages, Genie's view layer is available; when it must not, keep the service JSON-only.
using Genie, Genie.Renderer.Html

# A page rendered from a template with variables
route("/items/page") do
    html(:items; items = load_items(), title = "Items")
end

# public/ holds static files: Genie serves them without a route
#   public/css/app.css      →  GET /css/app.css
#   public/index.html       →  GET /

# Inline HTML when a template is overkill
route("/ping") do
    html("<h1>pong</h1>")
end

# Rule of thumb:
#   an API for other programs → JSON only, no templates
#   a small admin page       → server-rendered HTML, no JavaScript build
#   a rich application       → JSON API plus a separate front end
The last rule prevents the most common architectural regret: a service that started as an API and grew a template layer, a static pipeline and an asset build, until it is two applications in one repository.
JSON, REST and Validation
An API is a contract. The contract is expressed in three things: the shape of the JSON, the meaning of the status codes, and what happens when the input is wrong.
JSON in Julia
JSON3.jl reads JSON into Julia structures and writes Julia values back, without an intermediate dictionary in the common case.
using JSON3

# Read: a JSON object behaves like a named tuple
data = JSON3.read("""{"id": 7, "tags": ["a", "b"], "score": 91.5}""")
data.id                # 7
data.tags              # ["a", "b"]
data[:score]           # 91.5

# Existence and defaults, since a missing key is not an error
get(data, :missing, nothing)

# Write: any Julia value with a natural mapping
JSON3.write((id = 7, ok = true, items = [1, 2, 3]))
JSON3.write(DataFrame(x = 1:2, y = ["a", "b"]))

# Structs map to objects — the typed way to define an API payload
using StructTypes

struct Item
    id    :: Int
    name  :: String
    score :: Float64
end
StructTypes.StructType(::Type{Item}) = StructTypes.Struct()

JSON3.write(Item(1, "widget", 91.5))
item = JSON3.read("""{"id":1,"name":"widget","score":91.5}""", Item)
item.name              # "widget", parsed into the struct

# Round-tripping with types is the point: an untyped Dict lets a typo
# in a field name travel all the way into production.
The struct-based form is worth the extra four lines: it turns "the client changed the field name" from a silent nothing into a parse error at the boundary, where it is cheap to see.
Designing REST Endpoints
A small set of conventions removes most of the discussion from API design.
# RESOURCES, not actions
#   GET    /items           → list          (200)
#   GET    /items/7         → one           (200 or 404)
#   POST   /items           → create        (201 + Location header)
#   PUT    /items/7         → replace       (200 or 204)
#   PATCH  /items/7         → partial edit  (200)
#   DELETE /items/7         → remove        (204 or 404)

# Handlers that follow the conventions
using HTTP, JSON3

function create_item(req::HTTP.Request)
    body = JSON3.read(String(req.body), Item)
    id   = store!(body)                                 # returns the new key
    return HTTP.Response(201,
        ["Content-Type" => "application/json",
         "Location"     => "/items/$id"],
        JSON3.write((id = id)))
end

function not_found(req::HTTP.Request)
    HTTP.Response(404, ["Content-Type" => "application/json"],
                  JSON3.write((error = "not_found", message = "no such item")))
end

# STATUS CODES THAT MEAN SOMETHING
#   200 ok  · 201 created  · 204 no content
#   400 malformed request  · 401 unauthenticated  · 403 forbidden
#   404 not found  · 409 conflict  · 422 validation failed  · 429 too many requests
#   500 your bug  · 503 dependency down

# PAGINATION: never return an unbounded list
#   GET /items?limit=50&offset=100
#   response: { items: [...], total: 1234, limit: 50, offset: 100 }
The pagination rule is the one that bites in production: an endpoint that returns "all items" works fine with a hundred rows and takes down the database with a million.
Validating Input
Every field that arrives from the network is hostile until proven otherwise. Validate once, at the boundary, and keep the rest of the code free of defensive checks.
using HTTP, JSON3

struct ItemInput
    name  :: String
    score :: Float64
end

function parse_item(body::AbstractString)
    data = try
        JSON3.read(body)
    catch
        return (ok = false, error = "malformed JSON")
    end

    haskey(data, :name)  || return (ok = false, error = "name is required")
    haskey(data, :score) || return (ok = false, error = "score is required")

    name = string(data.name)
    isempty(strip(name)) && return (ok = false, error = "name must not be empty")

    score = try
        Float64(data.score)
    catch
        return (ok = false, error = "score must be a number")
    end
    (0.0 <= score <= 100.0) || return (ok = false, error = "score must be between 0 and 100")

    return (ok = true, value = ItemInput(name, score))
end

# In the handler, validation failure is a 422 with a reason — never a 500
function post_item(req::HTTP.Request)
    parsed = parse_item(String(req.body))
    if !parsed.ok
        return HTTP.Response(422, ["Content-Type" => "application/json"],
                             JSON3.write((error = "validation_failed", detail = parsed.error)))
    end
    item = parsed.value
    HTTP.Response(201, JSON3.write((name = item.name)))
end

# Rules that keep validation honest:
#   - reject unknown fields rather than ignoring them silently
#   - cap the request body size before parsing it
#   - never echo user input back into an error message unescaped
Distinguishing 422 from 400 is a courtesy to clients: 400 says "your request is not valid HTTP or JSON", 422 says "the JSON is fine, but the values are not acceptable". Good clients act on that difference.
Concurrency in Services
A web service spends most of its life waiting: for a database, for another API, for a disk. Julia's task scheduler makes that waiting nearly free — and the skill is knowing which work must not share a thread.
Async Request Handling
Each request runs in its own task. Blocking I/O yields; CPU-bound work does not.
using HTTP

# HTTP.jl already serves each connection in a task, so a handler that
# awaits I/O does not block other requests.
function slow_handler(req::HTTP.Request)
    a = @async fetch_from_service_a()      # both requests start
    b = @async fetch_from_service_b()
    results = (fetch(a), fetch(b))         # then we wait for both
    HTTP.Response(200, join(results, "\n"))
end

# Bounded concurrency: at most 8 outbound calls at a time
const SEM = Base.Semaphore(8)
function bounded_fetch(url)
    Base.acquire(SEM)
    try
        return HTTP.get(url; readtimeout = 5)
    finally
        Base.release(SEM)                  # always released, even on error
    end
end

# Fan out over many items without launching thousands of tasks
function fetch_many(urls)
    tasks = [@async bounded_fetch(u) for u in urls]
    return fetch.(tasks)
end

# THE RULE THAT MATTERS
#   I/O-bound handler  → @async / async I/O          (thousands of requests)
#   CPU-bound handler  → Threads.@spawn with N≈cores (a few concurrent jobs)

# A CPU-bound handler on the async scheduler blocks every request on that
# thread. Start Julia with threads, then move the work:
#   julia --threads=4 server.jl
using Base.Threads
function heavy_handler(req::HTTP.Request)
    t = Threads.@spawn expensive_computation(job_id(req))
    HTTP.Response(200, string(fetch(t)))
end
The distinction between these two calls — @async and Threads.@spawn — is the difference between a service that scales to a thousand slow clients and one that freezes under a single expensive computation.
Databases and Connection Pools
A database connection is a shared, stateful resource. Concurrent handlers must not share one connection without either a pool or a lock.
using SQLite, DBInterface, DataFrames

# One connection, one writer: SQLite serialises writes anyway.
# Guard it with a lock rather than letting tasks interleave statements.
const DB = SQLite.DB("app.db")
const DB_LOCK = ReentrantLock()

function get_item(id::Int)
    lock(DB_LOCK) do
        row = DBInterface.execute(DB, "SELECT * FROM items WHERE id = ?", (id,))
        DataFrame(row)
    end
end

# For a server database (PostgreSQL via LibPQ.jl), use a pool instead
using LibPQ
const POOL = LibPQ.ConnectionPool("host=localhost dbname=app", 10)

function query_items()
    LibPQ.with_connection(POOL) do conn
        DataFrame(LibPQ.execute(conn, "SELECT * FROM items LIMIT 50"))
    end
end

# Rules that prevent connection exhaustion:
#   - a pool size matched to the database's limit, not to traffic
#   - always release in a `finally` block or a `do` block
#   - prepared statements for anything called per request
#   - timeouts on queries, so one slow query cannot hold a connection
The do-block pattern is the safest form: the connection is returned even if the query throws. Hand-managed acquire/release pairs are how a service runs out of connections at 3 a.m.
Background Work and Cancellation
Work that takes longer than a request should not happen inside the request. Queue it, return 202 Accepted, and let the client poll.
using HTTP, JSON3, Dates

# A naive in-process job queue — enough for one node, and honest about it
const JOBS  = Dict{String,NamedTuple}()
const QUEUE = Channel{String}(100)

function submit_job(spec)
    id = string(hash((spec, now())))
    JOBS[id] = (status = "queued", result = nothing, submitted = now())
    put!(QUEUE, id)
    return id
end

# A worker task started once, at boot
function worker_loop()
    for id in QUEUE
        job = JOBS[id]
        JOBS[id] = (job..., status = "running")
        try
            result   = run_analysis(id)                # the slow part
            JOBS[id] = (job..., status = "done", result = result)
        catch err
            @error "job failed" id = id err = err
            JOBS[id] = (job..., status = "failed", result = nothing)
        end
    end
end
@async worker_loop()

# The HTTP surface for it
route("/jobs", POST) do
    id = submit_job(JSON3.read(String(req.body)))
    HTTP.Response(202, JSON3.write((id = id, status = "queued")))
end

route("/jobs/:id", GET) do
    id = params(:id)
    haskey(JOBS, id) || return HTTP.Response(404, "unknown job")
    JSON3.write(JOBS[id])
end

# What this design gives you
#   202 Accepted instead of a request that times out
#   a status the client can poll without blocking anything
#   one place where slow work is bounded — the single worker

# What it does NOT give you: survival across a restart, or a second node.
# For those, use a real queue (Redis, RabbitMQ) — the interface above is
# the same shape, only the Channel becomes a network resource.
The closing comment is the important one: the in-process queue is a fine first design and a poor last one. Advertising its limits in the code prevents a team from discovering them during an incident.
Beyond Plain HTTP
Three capabilities separate a toy API from a service a real client can build on: push, typed queries, and identity.
WebSockets
A WebSocket is a long-lived, bidirectional connection — the right tool when the server must push without being asked.
using HTTP, HTTP.WebSockets

# The server: keep a set of live connections and write to them
const CLIENTS = Set{WebSockets.WebSocket}()

function ws_handler(ws::WebSockets.WebSocket)
    push!(CLIENTS, ws)
    try
        for msg in ws                       # iterate incoming frames
            @info "client said" msg = msg
            WebSockets.send(ws, "echo: $msg")
        end
    finally
        delete!(CLIENTS, ws)                # always drop the closed connection
        @info "client disconnected" remaining = length(CLIENTS)
    end
end

HTTP.serve("0.0.0.0", 8081) do req::HTTP.Request
    if HTTP.WebSockets.isupgrade(req)
        WebSockets.open(ws_handler, req)
        return
    end
    HTTP.Response(404, "not a websocket endpoint")
end

# Broadcast to everyone from anywhere in the process
function broadcast_message(text)
    dead = WebSockets.WebSocket[]
    for ws in CLIENTS
        try
            WebSockets.send(ws, text)
        catch
            push!(dead, ws)                 # a failed send means a lost client
        end
    end
    foreach(ws -> delete!(CLIENTS, ws), dead)
end
The finally block and the dead-client sweep are not decoration: a WebSocket server that leaks closed connections eventually refuses new ones, and the failure appears hours after the bug that caused it.
GraphQL, gRPC and Binary Protocols
REST is the default, not the only option. Two alternatives solve specific problems well.
| Protocol | What it gives you | Choose it when |
|---|---|---|
| REST + JSON | Universally understood, cacheable, easy to debug | The default choice, especially for public APIs |
| GraphQL | The client states the fields it wants; one endpoint | Many clients with different data needs |
| gRPC | Binary, schema-driven, streaming, code generation | Service-to-service calls, performance-sensitive |
| WebSocket | Server push over one long connection | Live updates, chat, progress streams |
# gRPC with Julia: define the schema once, generate both sides
#   item.proto
#     service Items {
#       rpc Get (GetRequest) returns (Item);
#       rpc Stream (GetRequest) returns (stream Item);
#     }
#
# then generate the Julia stubs and implement the service:
function get_item(req)
    Item(id = req.id, name = "item-$(req.id)")
end

# The payoff is the generated code: client and server agree on the
# message types because neither of them wrote them by hand.

# In practice for a Julia service:
#   REST/JSON  → external clients, documentation, browser access
#   gRPC       → internal calls between your own services
#   WebSocket  → progress and live data to a user interface
A service may legitimately use two of these. What it should not do is invent its own transport: every protocol in the table already has clients, tooling, and debugging aids that a bespoke format will never acquire.
Authentication and Rate Limiting
Two questions must be answered before a service is exposed: who is calling, and how often may they call.
using HTTP, JSON3, SHA

# 1. Bearer token check, as middleware around the handler
function authorize(req::HTTP.Request)
    header = HTTP.header(req, "Authorization", "")
    startswith(header, "Bearer ") || return (ok = false, code = 401, msg = "missing token")
    token = split(header, ' ')[2]
    haskey(TOKENS, token) || return (ok = false, code = 401, msg = "invalid token")
    return (ok = true, user = TOKENS[token])
end

function protected_handler(req::HTTP.Request)
    auth = authorize(req)
    auth.ok || return HTTP.Response(auth.code, auth.msg)
    HTTP.Response(200, JSON3.write((user = auth.user, data = [])))
end

# 2. Never store passwords as they arrive: salt, then hash
salt   = rand(UInt8, 16)
stored = SHA.sha256(vcat(salt, Vector{UInt8}("user-password")))

# Prefer Argon2 or bcrypt from the ecosystem for real deployments:
# a single SHA-256 round is fast, and fast is the wrong property for passwords.

# 3. Rate limiting: a token bucket per client, in memory
const BUCKETS = Dict{String,Tuple{Float64,Float64}}()      # tokens, last refill
const RATE, CAPACITY = 5.0, 20.0                           # per second, burst

function allow_request(client)
    tokens, last = get(BUCKETS, client, (CAPACITY, time()))
    now_t  = time()
    tokens = min(CAPACITY, tokens + (now_t - last) * RATE)
    if tokens < 1.0
        BUCKETS[client] = (tokens, now_t)
        return false
    end
    BUCKETS[client] = (tokens - 1.0, now_t)
    return true
end

# Answer 429 with a Retry-After header so clients back off gracefully
#   HTTP.Response(429, ["Retry-After" => "1"], "too many requests")
Serving over TLS is not optional once passwords or tokens are involved: put the Julia service behind a reverse proxy such as nginx or Caddy, terminate TLS there, and let the proxy forward plain HTTP on the loopback interface.
Deploying a Julia Service
A service is not finished when it answers a request locally. It is finished when somebody else can start it, watch it, and stop it.
Configuration, Secrets and Startup
Configuration comes from the environment; secrets never come from the repository.
# config.jl — one place where the environment is read
struct Config
    host      :: String
    port      :: Int
    database  :: String
    log_level :: Symbol
    workers   :: Int
end

function load_config()
    Config(
        get(ENV, "APP_HOST", "127.0.0.1"),
        parse(Int, get(ENV, "PORT", "8080")),
        get(ENV, "DATABASE_URL", "sqlite://app.db"),     # never hard-code a password
        Symbol(get(ENV, "LOG_LEVEL", "info")),
        parse(Int, get(ENV, "APP_WORKERS", "1")),
    )
end

const CFG = load_config()

# Typing the configuration means a mistyped PORT fails at boot, not at the
# first request: `parse(Int, ...)` above is the whole mechanism.

@info "configuration loaded" host = CFG.host port = CFG.port
The typed Config struct turns configuration errors into a startup failure. A service that refuses to boot because PORT is not a number is much easier to operate than one that fails on the first request at 2 a.m.
Logging, Health and Shutdown
Three endpoints and one signal are what an orchestrator needs from you.
using HTTP, JSON3

# 1. Liveness: is the process alive?
route("/health") do
    HTTP.Response(200, "ok")
end

# 2. Readiness: can it do its job? Check dependencies, cheaply.
route("/ready") do
    db_ok = try
        DBInterface.execute(DB, "SELECT 1")
        true
    catch
        false
    end
    HTTP.Response(db_ok ? 200 : 503, JSON3.write((database = db_ok)))
end

# 3. Structured request logging as middleware
function log_requests(handler)
    return function (req::HTTP.Request)
        t0  = time_ns()
        res = try
            handler(req)
        catch err
            @error "unhandled exception" path = req.target err = err
            HTTP.Response(500, "internal error")
        end
        @info "request" method = req.method path = req.target status = res.status ms = round((time_ns() - t0) / 1e6, digits = 1)
        return res
    end
end

# 4. Graceful shutdown: on an interrupt, stop accepting and drain
server = HTTP.serve!(log_requests(route), CFG.host, CFG.port)
try
    while true
        sleep(3600)
    end
catch err
    err isa InterruptException || rethrow()
    @info "draining connections"
    close(server)                      # stop accepting, finish in-flight work
    @info "shutdown complete"
end
Logging one line per request with a duration is the cheapest observability there is. When the service becomes slow, that log tells you which endpoint and how slow — before any monitoring system is installed.
Common Pitfalls
The mistakes below are the standard reasons a Julia service works locally and fails in production.
| Pitfall | Consequence | Fix |
|---|---|---|
CPU work inside an @async handler | Every request on that thread stalls | Threads.@spawn with --threads=N |
| No timeout on outbound calls | One slow dependency becomes your outage | readtimeout on every call |
| Global mutable state shared across requests | Data races and cross-request bugs | Locks, per-request state, or a database |
| Compiling on the first request | Seconds of latency at the worst moment | Precompile and warm the paths you care about |
| Returning an unbounded list | Memory spikes and slow responses | Paginate everything |
| Logging secrets or full request bodies | Credentials in log aggregators | Log identifiers and status, not payloads |
| No health endpoint | An orchestrator cannot tell live from dead | /health and /ready |
| Hard-coded ports and passwords | One image cannot serve two environments | Read everything from the environment |
Each of these is a one-line fix and a multi-hour incident. Adopting them at the start costs an afternoon; retrofitting them during an outage costs the outage.
HTTP.jl is both client and server: set timeouts on every call, reuse a Client for connection pooling, retry only idempotent requests, and handle transport errors, status codes and malformed bodies separately. A minimal service is a router plus handlers; Genie.jl adds controllers, templates and hot reloading when the service grows. Define API payloads as structs, follow REST conventions, return honest status codes, paginate every list, and validate all input at the boundary with 422 on failure. Serve I/O-bound handlers with @async and CPU-bound work with Threads.@spawn, guard shared database connections with a pool or a lock, and move slow work to a queue behind 202 Accepted. Add WebSockets only when you need push, choose gRPC for internal calls, gate everything behind token authentication and rate limiting, and finish with environment-based configuration, structured request logging, /health and /ready endpoints, and a graceful shutdown on signal.
Next, ship it: Deployment & Packaging turns a working service into a release.